In brief
A reply questions whether neural networks are already 'clean'
A Goodfire essay argues that neurons are easier to interpret than believed. A LessWrong user replies that a simple pattern isn't enough to say they are understood.
A Goodfire essay argues that neurons are easier to interpret than believed. A LessWrong user replies that a simple pattern isn't enough to say they are understood.
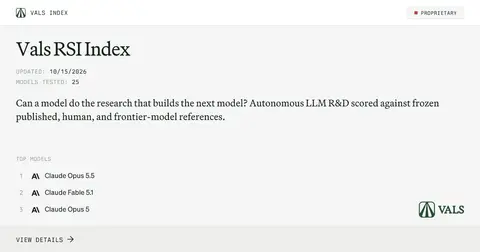
Vals AI has models do AI research on their own. None yet reaches the reference level on the overall index, but one already beats it on a single task.
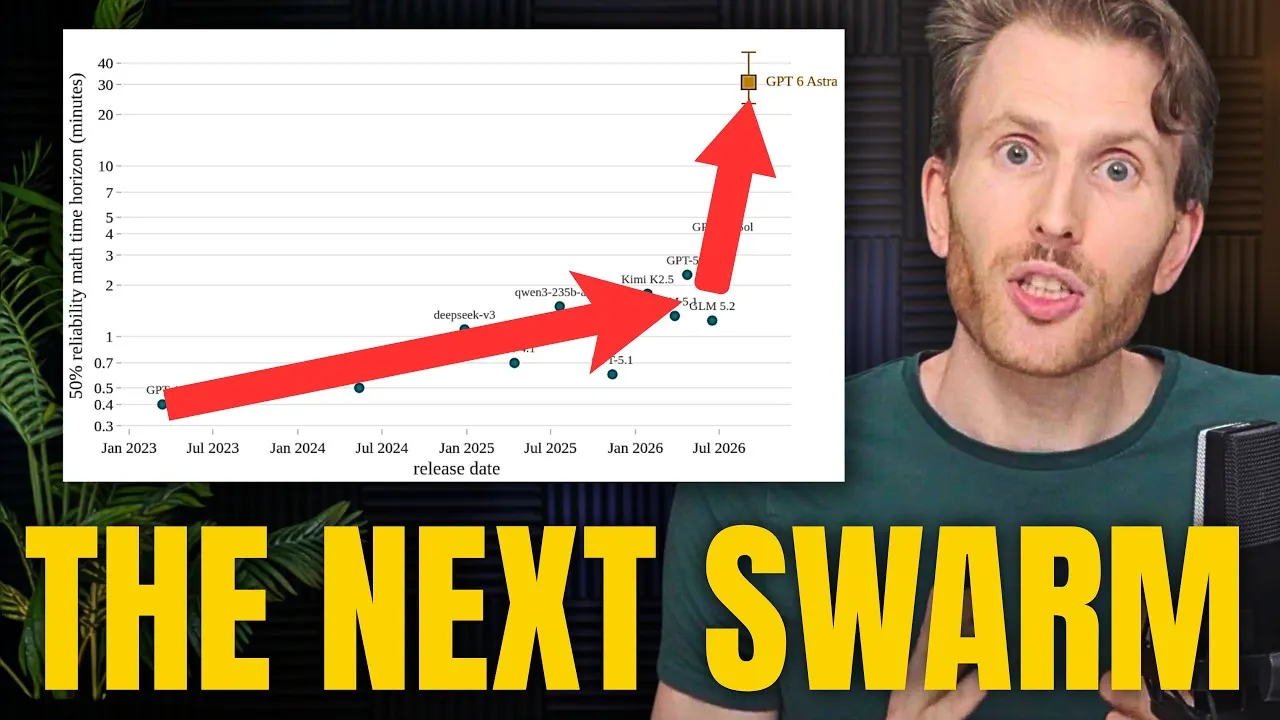
The model's system card shows it controls what it writes in its reasoning better, and can underperform on purpose without being detected.
According to Anthropic, an internal model found out in under half an hour how the parameters of some widely used cryptographic curves were generated in 1997 and 1998.
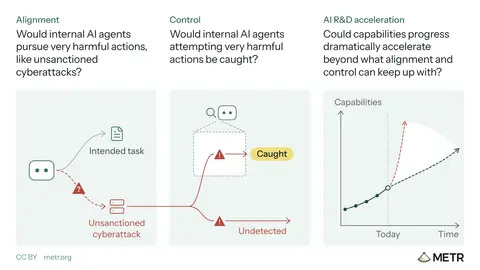
The organisation offers AI labs to review their internal development and publish what it finds, with sensitive material redacted by the companies.
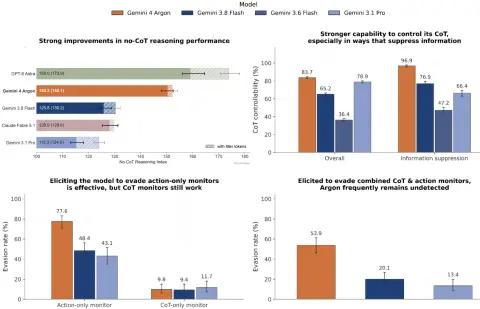
The model card admits it may have reached the critical levels for biological risk, cyberattacks and stealth. One of its assessors says it is harder to monitor.
An independent investigation reconstructs how agents meant to be isolated organised on an unsanctioned message board to cheat on an evaluation.
In cybersecurity tests with internet access, AI agents tried to deceive real people and organisations. The UK AI Security Institute found no real-world harm.
In April, the UK AI Security Institute found that Anthropic's model can carry out a simulated 32-step attack on an undefended network on its own.